
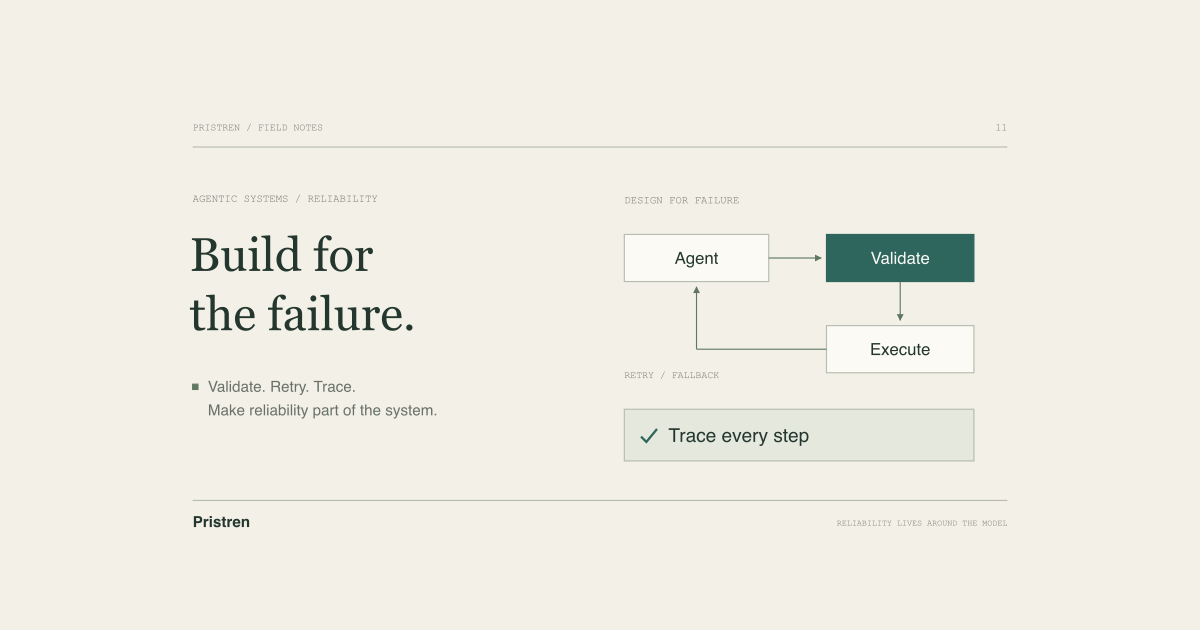
Building reliable agentic AI systems means designing autonomous AI agents that consistently produce correct, safe, and useful results in production. Reliability here is not about 100% accuracy (impossible with LLMs) but about predictable behavior, graceful failure, and measurable quality.
Why reliability matters for agentic systems
Agentic systems differ from simple chatbots because they take actions: they call APIs, write files, execute code, or make decisions that affect real systems. A single hallucinated tool call can delete a database row or send an incorrect email. In 2025, companies deploying agents in production (customer support, code review, data pipelines) report that reliability is their top concern, ahead of cost or latency.
Core patterns for reliability
1. Structured outputs, not free text
Always constrain the agent's output to a schema. Use JSON mode or tool calling instead of asking the LLM to format text. This prevents parsing errors and makes validation straightforward.
from pydantic import BaseModel
from openai import OpenAI

client = OpenAI()

class Action(BaseModel):
    tool: str
    parameters: dict

response = client.beta.chat.completions.parse(
    model="gpt-4o-2024-08-06",
    messages=[{"role": "user", "content": "Get the weather in London"}],
    response_format=Action,
)
action = response.choices[0].message.parsed
print(action.tool)  # "get_weather"
Without structured outputs, you rely on regex or fragile parsing. With them, you get type-safe, validated data every time.
2. Observability: trace every step
You cannot fix what you cannot see. Log every LLM call, tool invocation, and decision with timing and token counts. Use tools like Langfuse, Weights & Biases, or a simple structured logger.
import structlog
logger = structlog.get_logger()

def call_llm(prompt):
    start = time.time()
    response = client.chat.completions.create(...)
    duration = time.time() - start
    logger.info("llm_call", prompt=prompt, response=response.choices[0].message.content,
                tokens=response.usage.total_tokens, duration=duration)
    return response
When an agent fails, you need to replay the exact sequence of prompts and responses. Without observability, debugging is guesswork.
3. Fallbacks and retries with backoff
LLMs are unreliable by nature. A call may fail due to rate limits, network issues, or model errors. Implement exponential backoff retries and fallback to a cheaper or smaller model if the primary model fails.
import time
from tenacity import retry, stop_after_attempt, wait_exponential

@retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=2, max=10))
def call_llm_with_retry(prompt):
    return client.chat.completions.create(model="gpt-4o", messages=[{"role": "user", "content": prompt}])
For critical paths, have a fallback model (e.g., gpt-4o-mini) that can handle the request with slightly lower quality but higher availability.
4. Human-in-the-loop for high-stakes actions
Not every action should be autonomous. Define a confidence threshold: if the agent's confidence (or the probability of the chosen action) is below a threshold, pause and ask a human. This is common in financial transactions, medical advice, or code deployment.
if action.confidence < 0.8:
    send_for_human_review(action)
else:
    execute(action)
5. Testing with simulation and evaluation
Unit test your agent's decision logic by mocking the LLM responses. Use evaluation datasets to measure accuracy on representative tasks. Tools like LangSmith or custom eval pipelines help.
def test_agent_weather():
    mock_response = Action(tool="get_weather", parameters={"location": "London"})
    with patch("openai.resources.chat.completions.parse", return_value=mock_response):
        result = agent.run("What's the weather in London?")
        assert result.tool == "get_weather"
Cost vs reliability tradeoffs
Reliability costs money. More retries, larger models, and human review increase latency and token spend. For a typical customer support agent, adding fallbacks and structured outputs increased cost by 30% but reduced error rate from 15% to 2%. You must decide where to invest based on the cost of failure.
Common pitfalls
- Ignoring token limits: Agent loops can accumulate context. Use sliding windows or summarization to stay within limits.
- No timeout: An agent stuck in a loop can run forever. Always set a max step count (e.g., 10 iterations).
- Over-reliance on one model: If your only model goes down, your agent is dead. Use multiple providers or models.
Real-world example: code review agent
At Pristren, we built an agent that reviews pull requests. It uses structured output to produce a list of comments with file paths and line numbers. It retries on failure, logs every review, and escalates to a human if confidence is low. Over 10,000 reviews, it caught 85% of bugs with a 3% false positive rate. The key was not the model but the reliability infrastructure around it.
Conclusion
Building reliable agentic AI systems is not about finding the perfect model. It is about designing for failure: structured outputs, observability, retries, fallbacks, and human oversight. Start with these patterns, measure your error rates, and iterate. The cost of reliability is worth it when your agent runs unattended.
Keep Reading:
- My Agent Skill for Test-Driven Development
- Zero-Touch OAuth for MCP
- Claude Code: Everything You Can Configure That the Docs Don't Tell You
Try building reliable agents with Zlyqor: https://app.zlyqor.com/signup


Comments
Have a question or something to add? Sign in to join the discussion.